Author: mike.church

  • Building Scalable Energy Platforms: Lessons From Real-World Deployments

    Building Scalable Energy Platforms: Lessons From Real-World Deployments

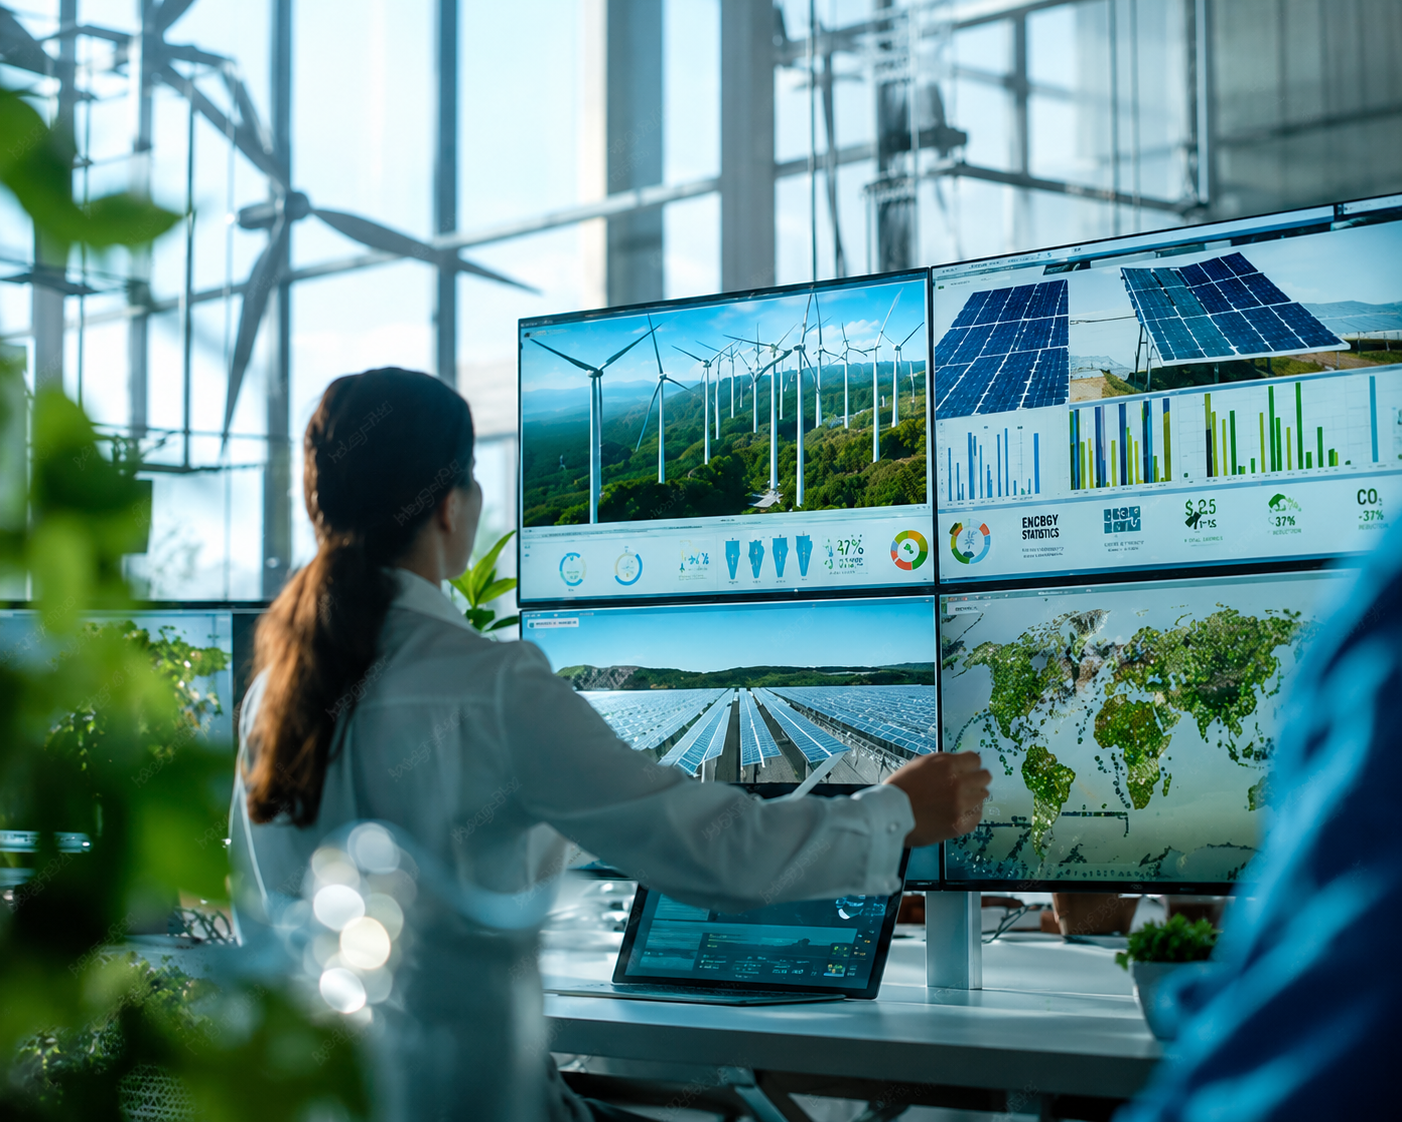
    Energy platforms fail at scale in ways that rarely show up in a proof-of-concept. A pilot running on a handful of substations or a few thousand smart meters can look flawless — clean dashboards, real-time data, happy stakeholders — and then break down completely when it’s rolled out across an entire grid region. The gap between “works in the pilot” and “works in production” is where most energy technology investments quietly lose their value.

    Having built and deployed platforms across utilities and energy operators, a few hard-earned lessons consistently separate the systems that scale from the ones that stall.

    Lesson 1: Data volume is not the real challenge – Data Variety Is

    It’s tempting to think scaling an energy platform is primarily a data-volume problem: more meters, more sensors, more time-series data, so you need more infrastructure. In practice, volume is the easy part — modern time-series databases and cloud infrastructure handle scale well.

    The harder problem is variety. A single utility might pull data from decades-old SCADA systems, newer IoT sensors, third-party weather feeds, customer billing systems, and regulatory reporting tools — each with different formats, different update frequencies, and different reliability guarantees. A platform that works beautifully against clean, simulated pilot data often falls apart when it meets the real heterogeneity of a utility’s actual systems.

    The lesson: design the data integration layer first, and design it for inconsistency. Build in validation, fallback logic, and graceful degradation for missing or delayed data from day one — not as a patch after the first production outage.

    Lesson 2: Real-Time Doesn’t Mean Instant Everywhere

    Energy platforms often get sold on the promise of “real-time visibility.” But not every part of a grid platform needs sub-second latency, and treating every data stream as equally time-critical is a common cause of overbuilt, expensive, and fragile architecture.

    Grid fault detection and protection systems may genuinely need millisecond-level responsiveness. Demand forecasting or billing reconciliation does not. A scalable platform separates these tiers deliberately — using event-driven architectures for the truly time-critical paths, and batch or near-real-time processing for everything else. Trying to force everything through the same low-latency pipeline drives up infrastructure cost without a corresponding operational benefit.

    Lesson 3: Interoperability Standards Aren’t Optional – They’re insurance

    Energy infrastructure outlives almost every other category of enterprise technology. A platform built today may still need to integrate with hardware and systems installed 15 years from now — and with vendors that don’t exist yet. This is precisely why standards like IEC 61850 for substation automation, or common information models for grid data exchange, matter more in energy than in most industries.

    Platforms built around proprietary, closed integrations may move faster initially, but they accumulate integration debt that becomes painfully expensive at scale — every new device type, vendor, or system requires custom work. Platforms built on open standards from the start pay a small upfront cost in flexibility for a much lower long-term cost in integration.

    Lesson 4: Scalability Is An Organizational Problem, Not Just a Technical one

    A platform can be architected perfectly and still fail to scale if the organization around it isn’t ready. Rolling out a platform from one pilot substation to hundreds of sites means more operators using the system, more edge cases surfacing, and more pressure on support and training.

    The deployments that scale successfully treat rollout as a phased, structured process: validating with a representative pilot group (not just the easiest sites), building feedback loops directly into the rollout plan, and investing in operator training and change management alongside the technology itself. The platforms that struggle tend to treat technical deployment and organizational adoption as separate workstreams instead of one coordinated effort.

    Lesson 5: Build for the Grid You’ll Have, not just the one you have

    Distributed energy resources, EV charging infrastructure, and bidirectional power flows are changing what “the grid” means structurally — not just in terms of data volume, but in terms of how the system needs to behave. A platform architected only around the assumptions of a traditional, one-directional grid will need a costly rebuild as DERs and distributed generation become mainstream.

    This doesn’t mean over-engineering for hypothetical future scenarios. It means making deliberate architectural choices — modular system design, flexible data models, API-first integration — that don’t lock the platform into assumptions that are already starting to break down.

    the Bottom line

    Scalable energy platforms aren’t built by solving for scale directly — they’re built by solving for variety, prioritization, interoperability, and organizational readiness, with scale as the natural result. The teams that treat their pilot as a finished product are usually the ones rebuilding from scratch eighteen months later. The teams that treat the pilot as the first data point in a longer architectural conversation are the ones whose platforms are still running, and still growing, years after deployment.
  • Modernizing Telecom Operations: Why Workflow Automation Matters More Than Ever?

    Modernizing Telecom Operations: Why Workflow Automation Matters More Than Ever?

    Telecom networks today look nothing like they did a decade ago. 5G densification, edge computing, fiber rollouts, and IoT-driven traffic have multiplied the number of moving parts that telecom operators need to manage — yet many of the operational workflows behind these networks are still running on processes designed for a simpler era. Provisioning a new service, activating a customer, or dispatching a field technician often still involves manual handoffs between systems, spreadsheets, and teams that were never built to talk to each other.
    This gap between network complexity and operational maturity is where workflow automation has shifted from a nice-to-have to a competitive necessity.

    The Hidden Cost Of Manual operations

    In most telecom organizations, the network itself is highly engineered — but the processes that keep it running are not. Service activation might require a technician to manually update three or four separate systems. A fault ticket might sit in a queue waiting for someone to triage it by hand before it’s even routed to the right team. Customer-facing changes — a plan upgrade, a new line, a service migration — can trigger a chain of back-office steps that depend on someone remembering to do them correctly, every time.

    The cost of this isn’t always visible on a balance sheet, but it shows up everywhere: longer time-to-activate for new services, inconsistent service quality across regions, higher mean-time-to-resolution for faults, and an operations team that spends more time chasing process than improving the network. As subscriber expectations rise and competition tightens margins, these inefficiencies compound.

    What Workflow automation actually solves

    Workflow automation isn’t about replacing engineers — it’s about removing the repetitive, rules-based work that shouldn’t require a human decision in the first place. In practice, this looks like:

    • Provisioning and service activation — automatically triggering the sequence of system updates needed when a new service is ordered, instead of relying on manual coordination across OSS/BSS systems.
    • Fault detection and routing — using rules and pattern recognition to triage incoples automatically and route them to the right team immediately, rather than after manual review.
    • Preventive maintenance — shifting from reactive truck rolls to scheduled, condition-based maintenance triggered by network performance data.
    • Customer service workflows — automating the back-end steps behind common requests (upgrades, troubleshooting, billing adjustments) so support teams can resolve issues in one interaction instead of escalating across departments.

    None of this requires a “rip and replace” of existing infrastructure. Done well, automation sits on top of and integrates with existing OSS/BSS and network management systems, orchestrating the workflows that connect them rather than replacing the systems themselves.

    Why Now, Specifically

    Three forces are converging to make this urgent rather than optional:

    First, network complexity is increasing faster than headcount. 5G, edge deployments, and hybrid fiber-wireless architectures mean more configuration points, more failure modes, and more operational overhead per subscriber — without a proportional increase in operations staff.

    Second, customer expectations have shifted. Subscribers compare their telecom provider’s responsiveness to the on-demand experience they get from consumer apps, not to other telecom providers from ten years ago. A multi-day provisioning window or a fault that takes days to resolve is no longer acceptable, regardless of network complexity behind the scenes.

    Third, the data needed to automate intelligently is now available. Modern network management and monitoring systems generate far more granular data than they did even five years ago. The bottleneck is no longer data availability — it’s the ability to act on that data through workflows that don’t require manual intervention at every step.

    Where to start

    The organizations that get the most value from automation don’t try to automate everything at once. They start with high-frequency, well-defined workflows — service activation, common fault categories, routine maintenance triggers — where the rules are clear and the volume justifies the investment. From there, automation expands into more complex, judgment-heavy processes as confidence and data quality improve.

    This is also where AI-enhanced capabilities add real value on top of traditional automation: predictive maintenance models that flag likely failures before they happen, or anomaly detection that catches network issues before they become customer-facing tickets. The goal isn’t AI for its own sake — it’s using the right tool, automation or intelligence, for each specific operational bottleneck.

    the bottom line

    Telecom operators don’t have an engineering problem — they have an operations problem. The networks are sophisticated; the workflows behind them often aren’t. Closing that gap through targeted workflow automation is one of the highest-leverage investments a telecom organization can make today: it reduces operational cost, improves service quality, and frees engineering and operations teams to focus on the work that actually requires human expertise.

    The providers that modernize their operational workflows now will be the ones positioned to scale efficiently as network complexity continues to grow. The providers that don’t will keep paying a manual-process tax that gets more expensive every year.

  • Engineering for Longevity: How to Build Software That Stands the Test of Time

    Engineering for Longevity: How to Build Software That Stands the Test of Time

    Most software isn’t killed by a single catastrophic bug. It dies slowly, from the accumulated weight of shortcuts taken under deadline pressure, dependencies nobody dares to update, and architecture decisions made for a six-month roadmap that the business outlived years ago. By the time anyone notices, the system isn’t just hard to change — it’s actively dangerous to touch.

    Building software that lasts isn’t about predicting the future correctly. It’s about making decisions today that don’t foreclose options tomorrow. A few principles consistently separate systems that age well from systems that become liabilities.

    Longevity Stars with saying no to the wrong abstractions

    There’s a common instinct to over-engineer for flexibility early — building elaborate plugin systems, configuration layers, or abstraction upon abstraction to handle requirements that don’t exist yet. This usually backfires. Premature abstraction is often more rigid than no abstraction at all, because it locks in guesses about future requirements that turn out to be wrong, and now there are two problems to unwind instead of one.

    Durable systems tend to start simple and concrete, and earn their abstractions through repetition — when the same pattern shows up three times, that’s the signal to abstract it, not before. The discipline isn’t building for every possible future; it’s keeping the code honest about what it actually needs to do right now, so that when requirements do change, the change is localized rather than systemic.

    dependencies are liabilities you choose to take on

    Every third-party library, framework, or service is a bet that someone else will maintain it as long as the software needs to run. Some of those bets pay off for a decade. Others become unmaintained, insecure, or incompatible within two years — and by then, the codebase has often grown so dependent on that choice that removing it is a multi-month project rather than a quick swap.

    Engineering for longevity means treating every dependency decision with the seriousness it deserves: favoring well-established, actively maintained options over the newest framework; isolating third-party code behind clear interfaces so it can be replaced without rewriting the application logic around it; and periodically auditing what’s actually load-bearing versus what was added for convenience and never reconsidered.

    tests are the only honest documentation

    Comments go stale. Wikis go stale. Onboarding docs go stale almost the moment they’re written. A test suite, by contrast, fails loudly the moment reality diverges from what it expects — which means it’s the only form of documentation with a built-in incentive to stay accurate.

    Systems that survive years of changing requirements and changing teams are almost always systems with strong test coverage at the right layers — not necessarily 100% coverage everywhere, but solid coverage of business logic and critical paths, so that a new engineer two years from now can change something with confidence instead of fear. Codebases without this safety net don’t get safer over time; they get more fragile, because every successive change is made by someone with less context than the last, working without a way to verify they haven’t broken something.

    operational visibility is part of the architecture, not an afterthought

    A system that works but can’t tell you why it’s slow, why it failed, or what it was doing right before an incident isn’t really finished — it’s just untested by production yet. Logging, monitoring, and tracing are often treated as something to bolt on later, which means they get designed under pressure, during an outage, by someone trying to understand a system that was never built to explain itself.

    Long-lived systems are built with observability as a first-class design concern from the start: structured logging, meaningful metrics, and clear error boundaries that make it possible to understand what’s happening in production without guessing. This isn’t just an operations convenience — it’s what allows a system to be debugged and improved for years without requiring the original authors to still be around.

    the business will change. the architecture should expect it

    Requirements shift, priorities get reprioritized, and the feature that justified an entire subsystem two years ago might be irrelevant today. Software that lasts doesn’t try to predict which specific changes are coming — it’s built with clear boundaries between components, so that the parts that need to change can change without dragging the rest of the system with them.

    This is less about following a specific architectural pattern and more about a habit of asking, at each decision point: if this assumption turns out to be wrong in eighteen months, how much does it cost to undo? Decisions that are cheap to reverse can be made quickly. Decisions that are expensive to reverse deserve more scrutiny up front.

    the bottom line

    Software that stands the test of time isn’t the software with the cleverest architecture or the newest stack — it’s the software built by engineers who treated maintainability, observability, and restraint as seriously as they treated features. Every shortcut taken to hit a deadline is a small loan against the system’s future; taken occasionally and paid down deliberately, that’s normal engineering. Taken constantly and never revisited, it’s how systems quietly become unmaintainable.

    The teams that build for longevity aren’t slower — they’re the ones still able to move quickly five years in, while everyone who optimized purely for speed at the start is rebuilding from scratch.